The Training Admission
In September, OpenAI's brief in the authors' copyright case against it was made public. In its own words, it used "compilations of books from Library Genesis" to train GPT-3 and GPT-3.5. A federal judge has called Library Genesis a pirate library.
The note.
The authors' filing quotes an internal note from 2019, written by an OpenAI employee: "We trained GPT-3 on pirated stuff! No sharing that!"
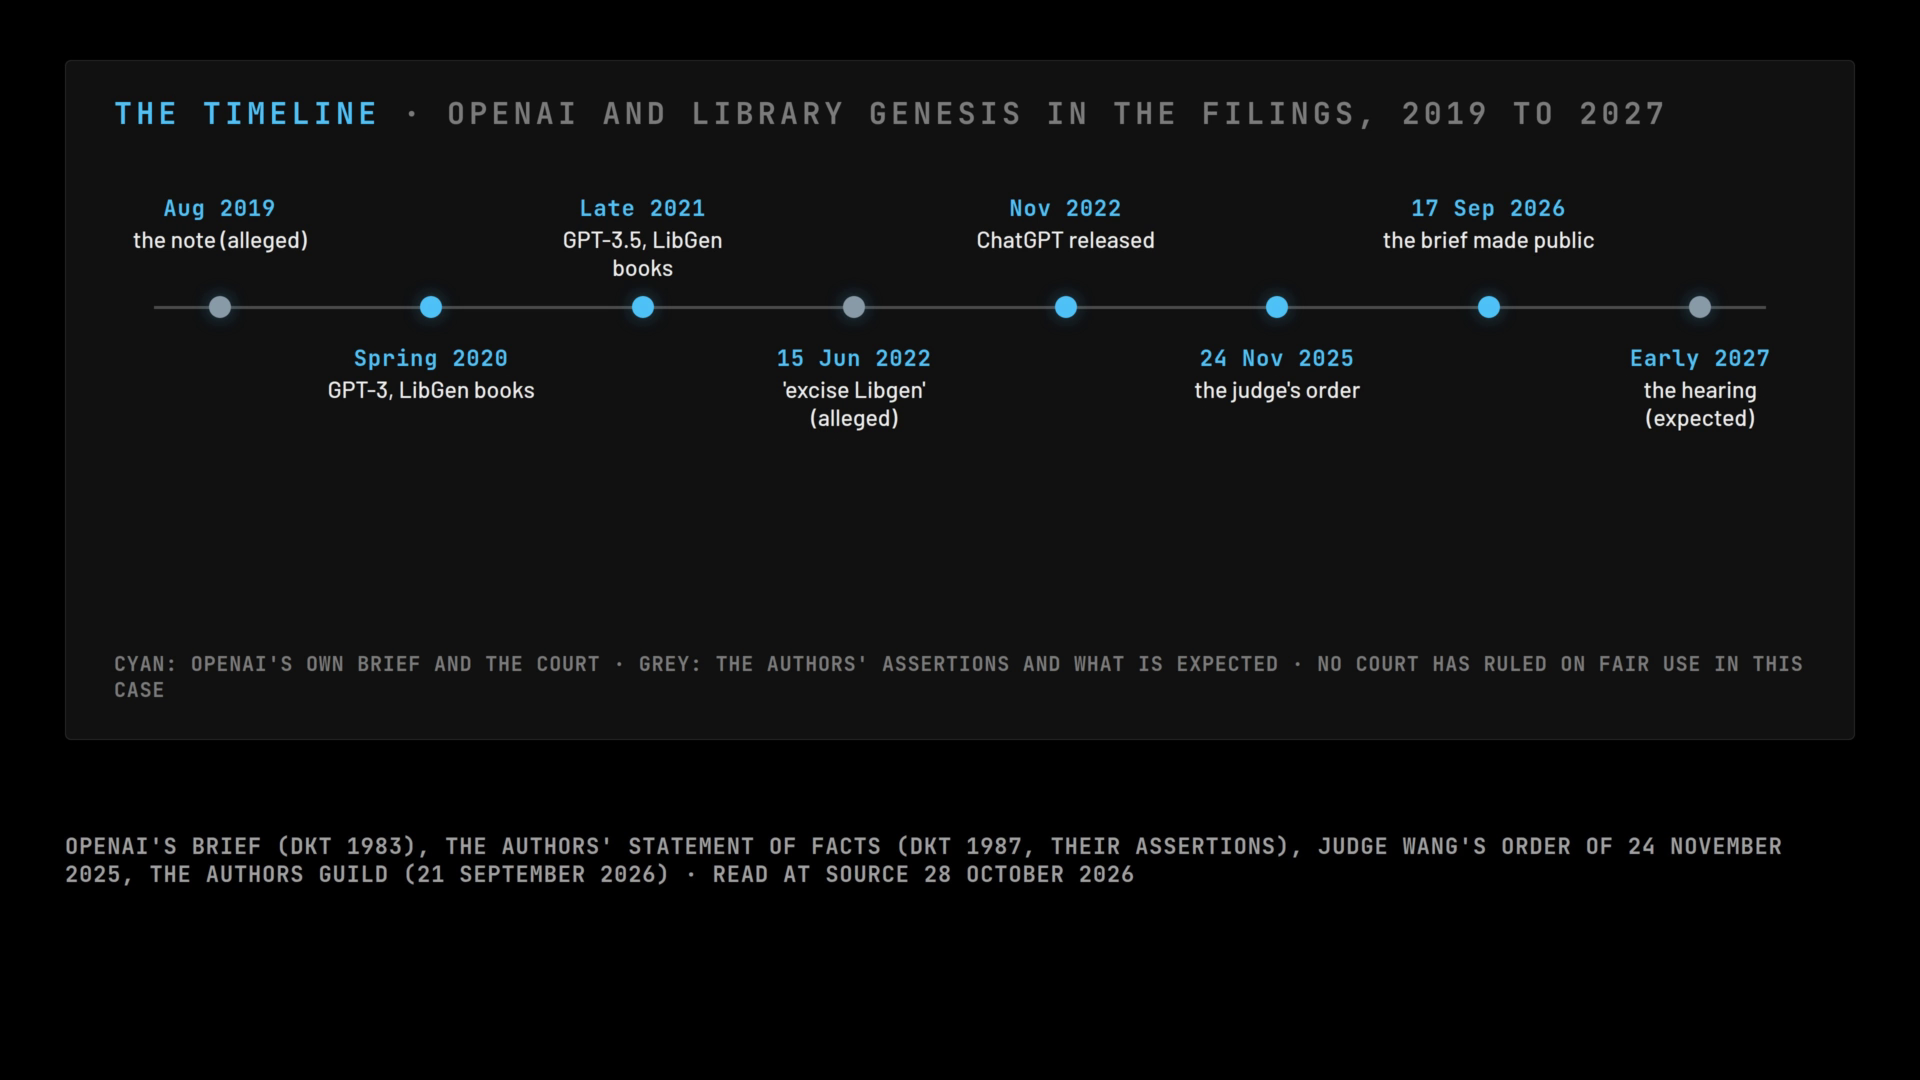
OpenAI's brief (Dkt 1983, p.8): "OpenAI used broader mixtures of data from the public Internet, including compilations of books from Library Genesis used in training GPT-3 (Spring 2020) and GPT-3.5 (late 2021), long before ChatGPT was released in November 2022." The brief was made public on 17 September 2026. The note is the authors' exhibit (their statement of facts, ¶344); its writer is not named here. A federal judge, William Alsup, wrote in Bartz v. Anthropic (23 June 2025) that Library Genesis copies "he knew had been pirated"; OpenAI calls that statement dicta, as reported.
The timeline.
In June 2022, five months before ChatGPT came out, the filing says OpenAI's then vice president of research wrote: "Given how much OpenAI is in the news, now is the right time to excise Libgen from our systems and storage."
The note (2019) and the 'excise Libgen' line (15 June 2022) are the authors' assertions. The full sentence, credited to Bob McGrew, then OpenAI's vice president of research, in the authors' statement of facts (¶312): "Given how much OpenAI is in the news, now is the right time to excise Libgen from our systems and storage. What would be involved in that?" OpenAI deleted Books1 and Books2 in 2022. Judge Wang (24 November 2025) ordered OpenAI to produce its communications on the reasons, and denied the authors' crime-fraud argument. No court has ruled on fair use in this case.
The depositions.
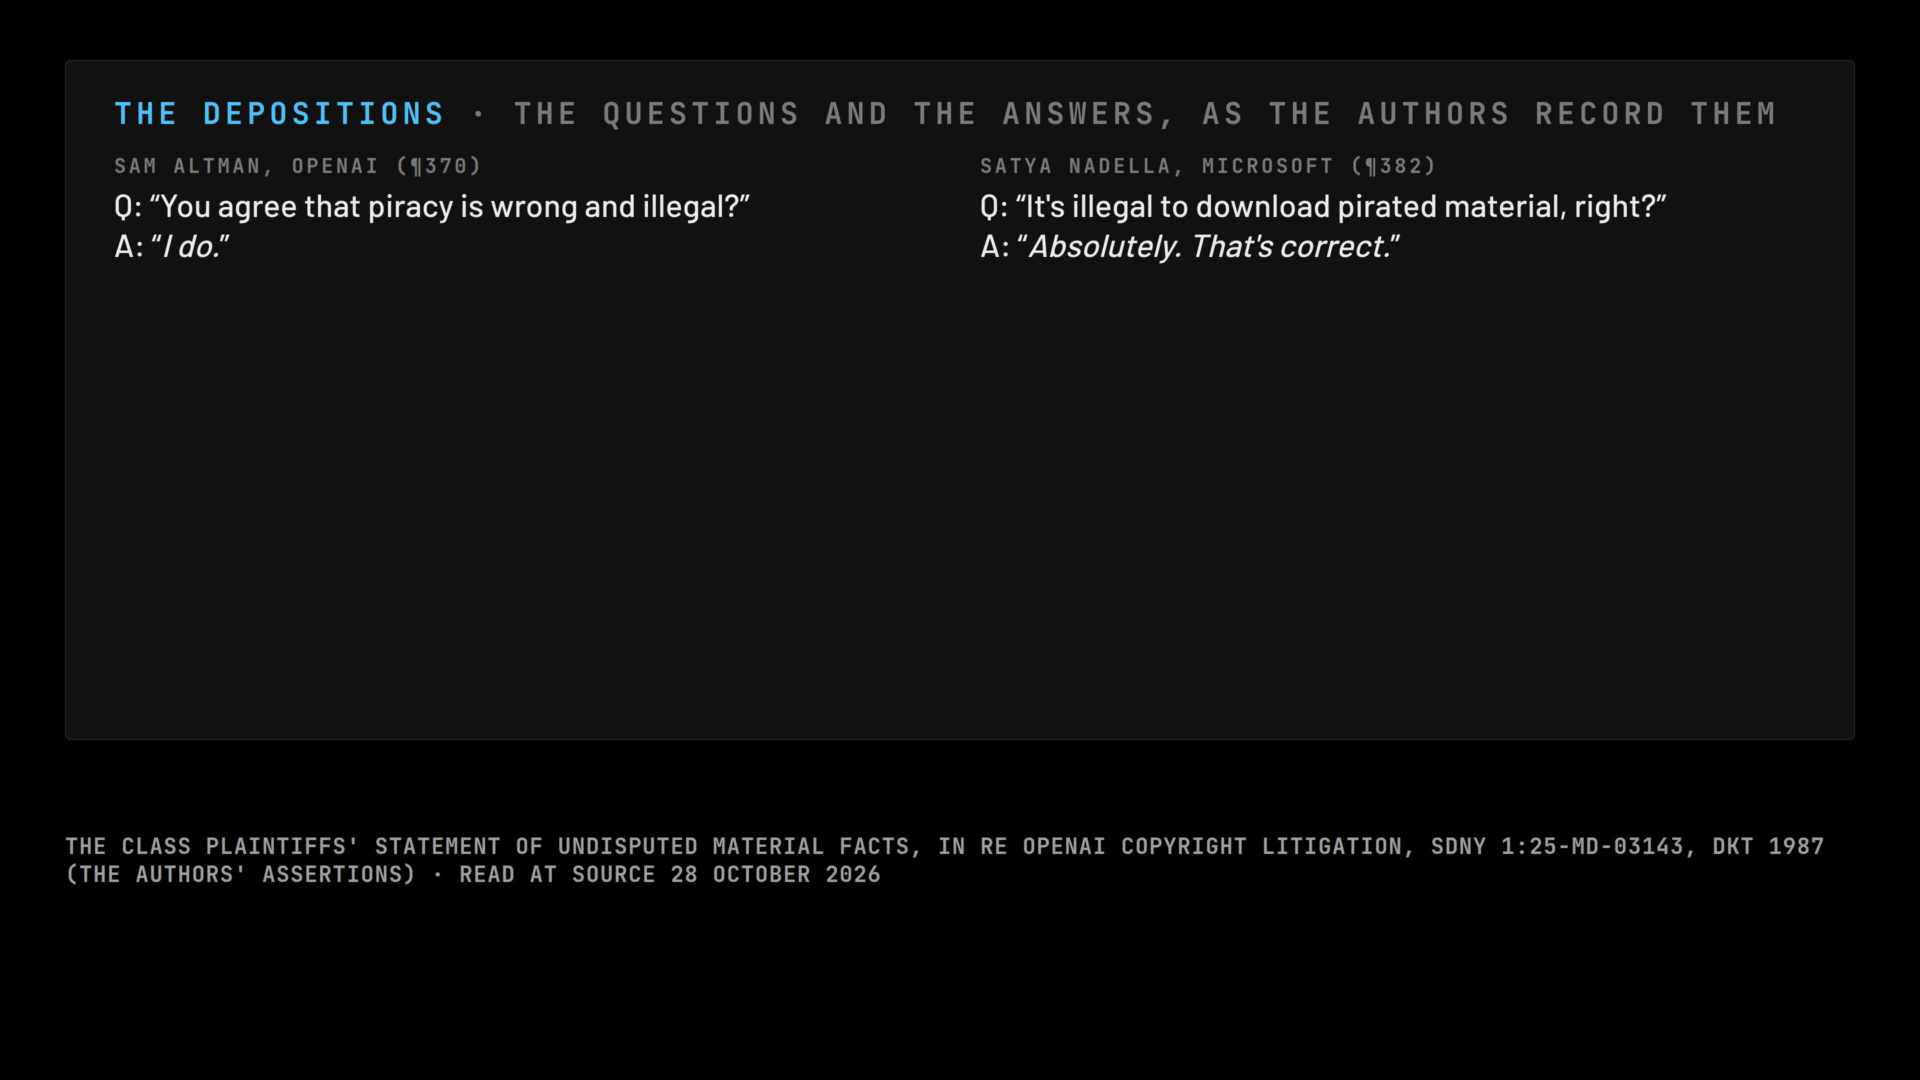
Under oath this year, Sam Altman was asked: "You agree that piracy is wrong and illegal?" His answer: "I do." Microsoft's Satya Nadella was asked: "It's illegal to download pirated material, right?" "Absolutely. That's correct."
As the authors record them (¶370 and ¶382). The authors also record (¶384) that Nadella "wish[ed] that OpenAI had not gone to a pirated site".
The defence.
OpenAI's answer: the downloading "was part of a single transformative use". In other words, fair use. It says no other model in the case was trained on the library. Microsoft says it "had no involvement at all in acquiring" the datasets.
OpenAI's brief, its heading: "2. OpenAI's downloading was part of a single transformative use." "No other LLMs at issue in this case were trained on material downloaded from Library Genesis" refers to the seven models in the case, GPT-3 to GPT-4o mini, not every later model. Microsoft (Dkt 1973, p.24): "Microsoft did not download—and indeed had no involvement at all in acquiring—the datasets from LibGen that OpenAI used in connection with the development of its early models." The authors allege Microsoft knew in April 2019.
Anthropic.
Anthropic, which makes Claude, the model Token Runner is built with, downloaded from pirate libraries too. In a 2025 ruling, a judge wrote that Anthropic "pirated over seven million copies of books." It settled with the authors for one and a half billion dollars, about three thousand dollars a work, without admitting it broke the law, and it must destroy the files. It says the pirated sets weren't in any model it released. And the authors' filing against OpenAI quotes Anthropic's chief executive, Dario Amodei, in 2020, when he was at OpenAI: "Is it sketchy to call our corpuses 'Books1' and 'Books2' and not say what they are?"
“…Anthropic thereby pirated over seven million copies of books…”
Judge William Alsup, summary-judgment order, 23 June 2025 (Bartz v. Anthropic), Dkt 231, p.3
Anthropic makes Claude. A disclosure: Token Runner is built with Claude. Judge Alsup's order (Dkt 231, p.3): "in July 2022, Anthropic likewise downloaded at least two million copies of books from the Pirate Library Mirror ... Anthropic thereby pirated over seven million copies of books"; and (p.18) it "kept these pirated copies in its library even after deciding it would not use them to train its AI". The same order held the training to be fair use and the pirated library copies not, and sent those to trial; the settlement followed. The settlement: $1.5 billion, "approximately $3,000" per work before fees and costs; 482,460 works listed, 440,490 claimed; final approval 20 July 2026. Its §10.6: "Class Members are not agreeing Anthropic acted lawfully ... and Anthropic is not agreeing that it acted unlawfully". Settled is not cleared. Amodei's full sentence (¶276, 15 May 2020): "Is it sketchy to call our corpuses 'Books1' and 'Books2' and not say what they are, particularly when in fact they are Libgen (which is a slightly sketchy source)." The authors also record (¶278) that he agreed OpenAI would "describe libgen as 'Books1' and 'Books2'", and Ben Mann's testimony (¶271): "Books2 is a dataset that I produced, and both are based on LibGen". Both men are now Anthropic co-founders; Amodei is its chief executive.
The others.
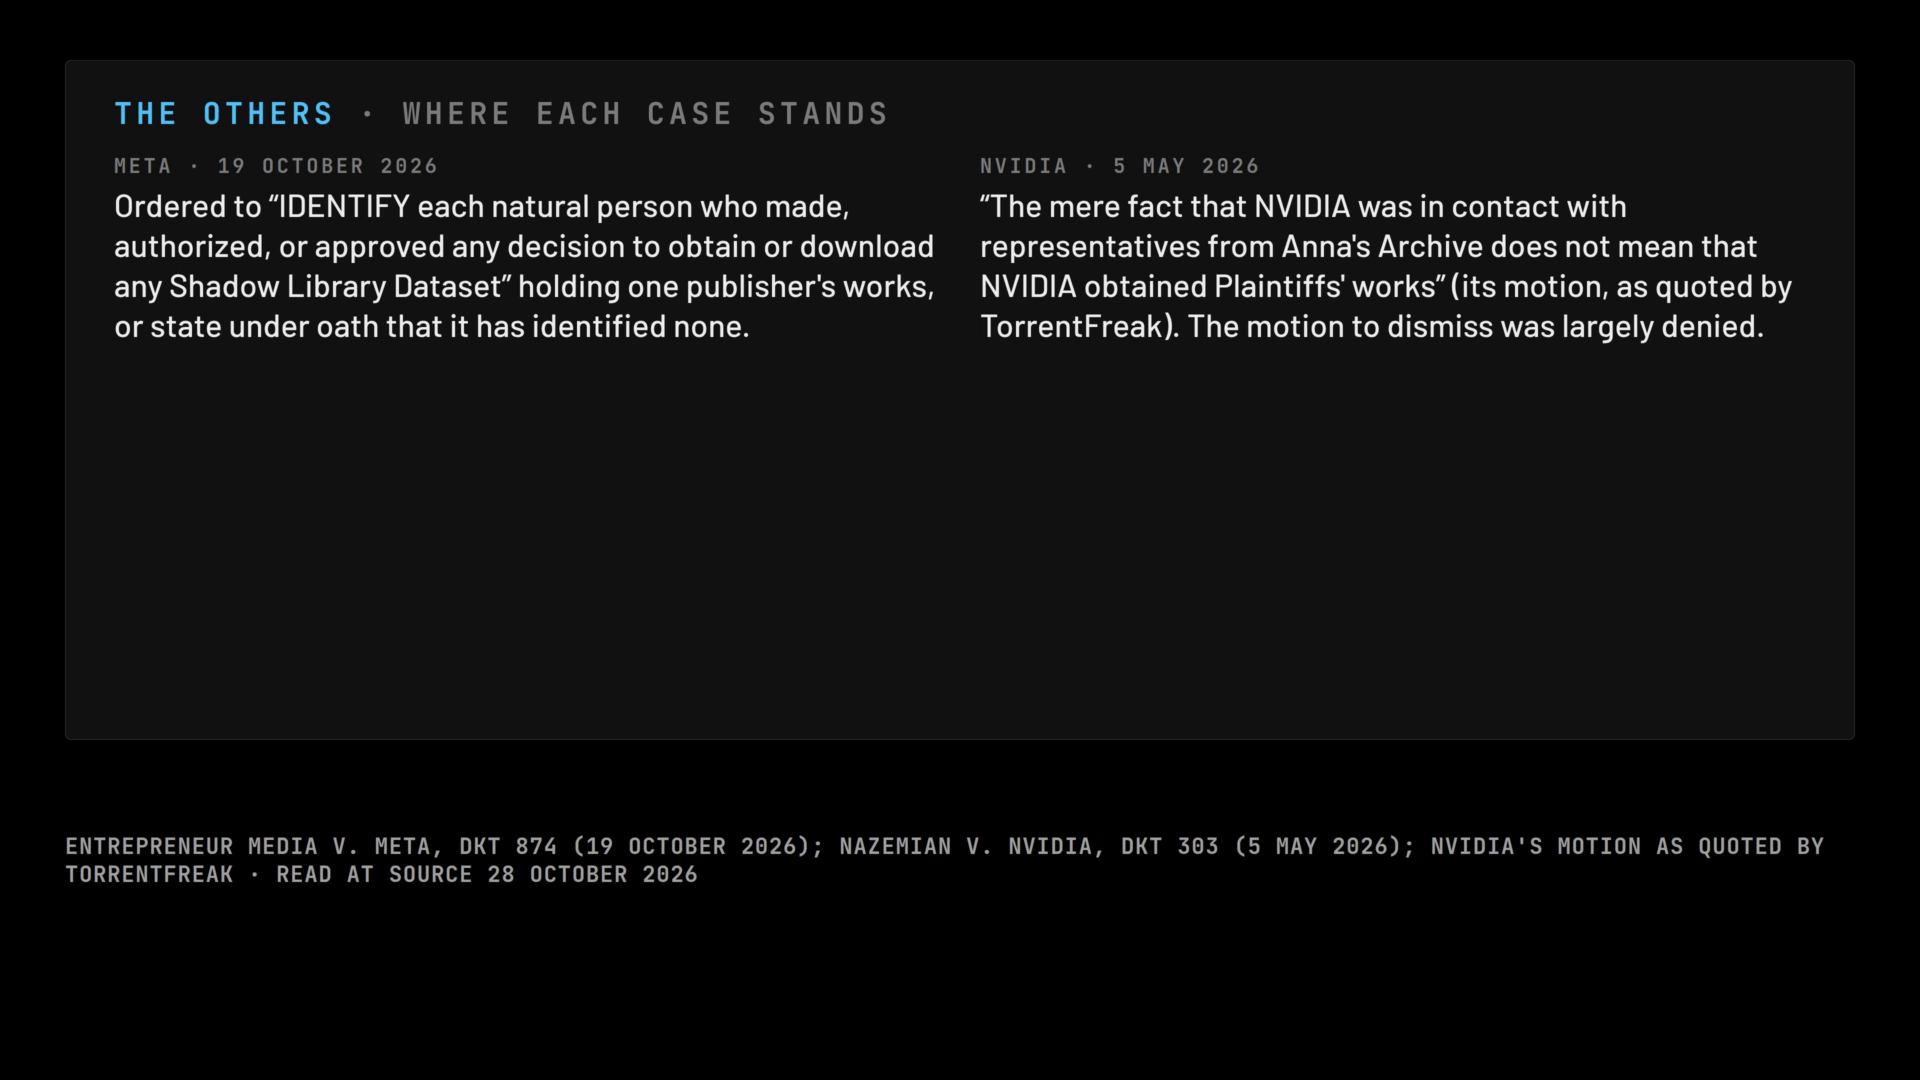
A judge has ordered Meta to name everyone who approved downloading pirate-library datasets holding one publisher's books, or swear it has found no one. Nvidia says contact with a pirate library doesn't mean it took the authors' books. Its case is going ahead.
Meta: the order (Dkt 874, p.6) grants the publisher's interrogatory: "IDENTIFY each natural person who made, authorized, or approved any decision to obtain or download any Shadow Library Dataset containing Plaintiff's Works ... or a statement under oath that Meta has identified none." In Kadrey v. Meta, the court ruled fair use for Meta in June 2025, as it did for Anthropic's training in Bartz. Nvidia: Judge Tigar (Dkt 303, 5 May 2026) denied its motion to dismiss on most claims. Its side, from its motion as quoted by TorrentFreak: "The mere fact that NVIDIA was in contact with representatives from Anna's Archive does not mean that NVIDIA obtained Plaintiffs' works from Anna's Archive."
Where it stands.
No court has yet ruled on whether OpenAI's training on those books was fair use. But OpenAI now says, in its own brief, where those books came from.
What we couldn't confirm: Nvidia's motion in its own text (quoted here as TorrentFreak quotes it), and the authors' oppositions of 23 October, reported by a secondary source. The hearing is expected in early 2027, as the Authors Guild expects.
Every quote from the court filings, with its source on screen. Token Runner dot A I.
Sources
- OpenAI's summary-judgment brief, In re OpenAI Copyright Litigation, SDNY 1:25-md-03143, Dkt 1983, p.8 (made public 17 September 2026). Read at source.
- Microsoft's brief, Dkt 1973, p.24. Read at source.
- The class plaintiffs' Statement of Undisputed Material Facts, Dkt 1987 (17 September 2026): the authors' assertions, ¶¶271, 276, 278, 312, 344, 370, 382, 384. Read at source.
- Judge Ona Wang's order of 24 November 2025 on the deletion of Books1 and Books2. Read at source.
- Bartz v. Anthropic, Judge William Alsup's summary-judgment order, Dkt 231 (23 June 2025), pp.3 and 18. The host refuses automated readers; the order was read at source on 28 October 2026.
- Bartz v. Anthropic, the settlement agreement, Dkt 363-3 (§10.6, no admission; ¶2.2, the destruction of files). Read at source.
- Bartz v. Anthropic, the order granting final approval, Dkt 680 (20 July 2026). Read at source.
- Entrepreneur Media v. Meta, discovery order, Dkt 874 (19 October 2026, Magistrate Judge Hixson). Read at source.
- Nazemian v. NVIDIA, Dkt 303 (5 May 2026, Judge Tigar). Read at source.
- TorrentFreak, quoting Nvidia's motion to dismiss of 29 January 2026. Read at source.
- The Authors Guild, 21 September 2026. Read at source.